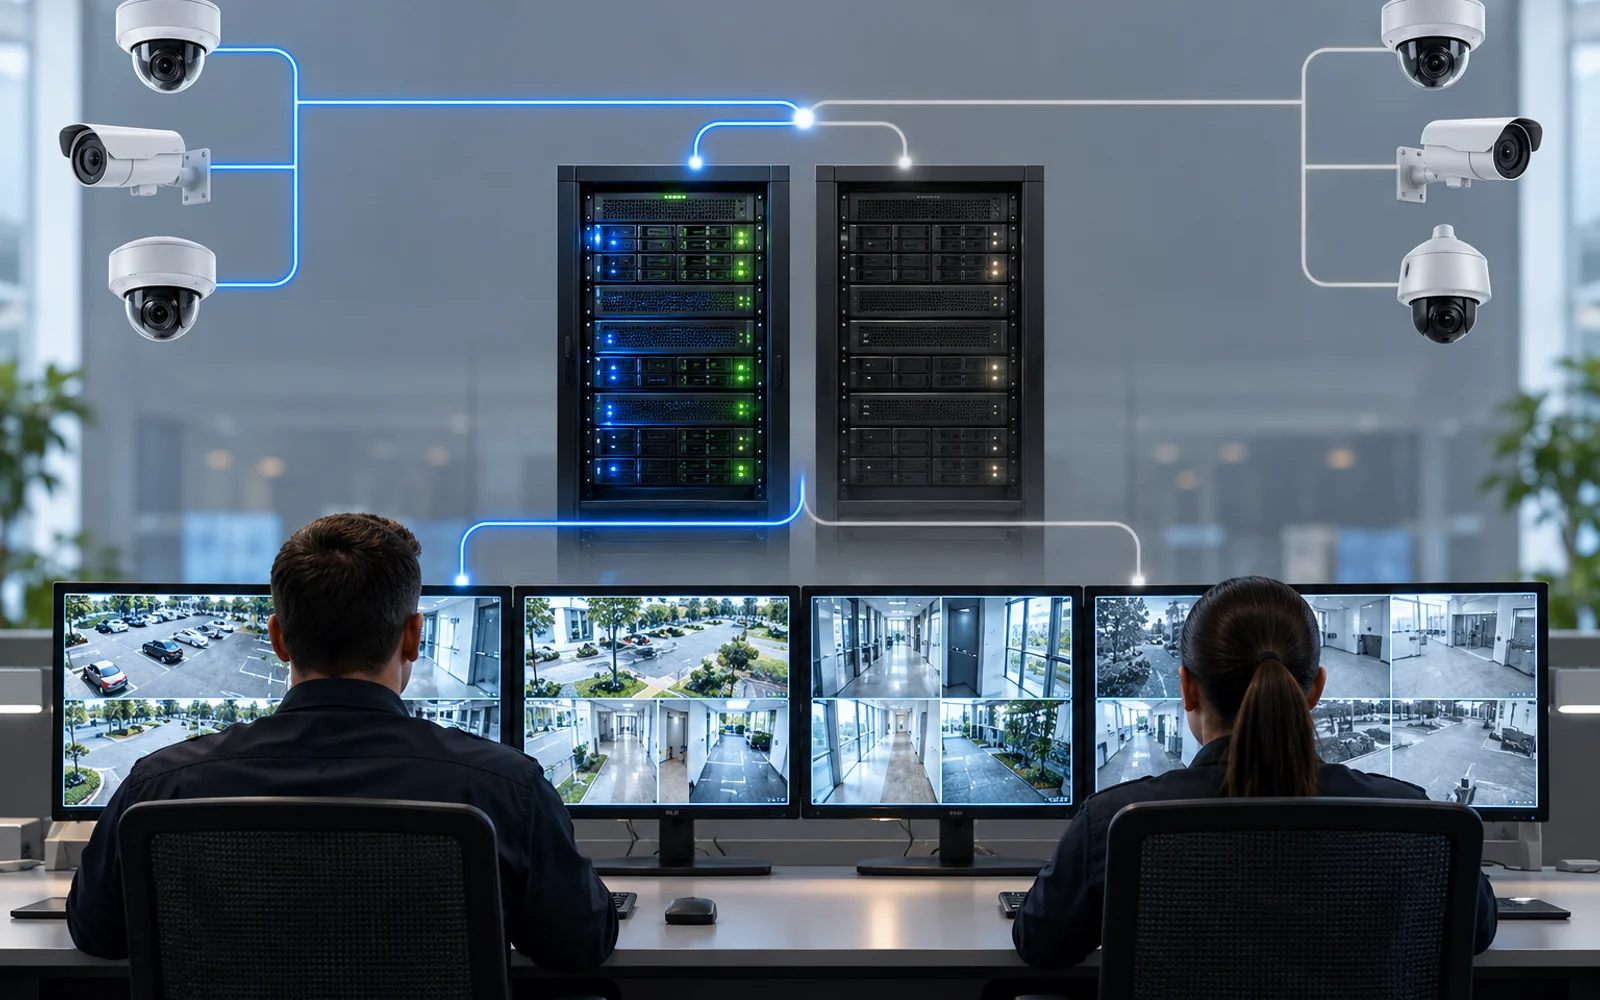
A secondary server is useful only if the required security functions continue or recover within agreed limits. Failover testing should measure detection, recording, event delivery and evidence retrieval separately. It should also prove that returning to normal service preserves data and restores the intended protection.
Table of Contents
What does the standby system actually protect?
Define the protected function and its dependencies before testing. A failover recorder may preserve video while a failed event broker prevents alarms from reaching operators. A second server on the same power and network path can share the original failure.
Milestone’s failover documentation distinguishes hot and cold standby and device-level failover support. It is a concrete example of why product configuration matters. Other platforms may allocate redundancy differently.
Map cameras and sensors, recording, analytics, event routing, identity, time service, storage and operator access. Identify which dependencies are protected and what remains outside the design.
Agree on recovery and data-loss limits
Define the maximum acceptable interruption for each function and the amount of data loss, if any, that the owner accepts. Recording, live viewing and event processing may need different limits.
Measure from a defined fault time to the restoration of a defined service. “Server online” is not the same as “new recording playable and exportable.” State whether recovery time includes detection, takeover, reconnect and backlog processing.
Do not promise zero loss merely because a product uses the term high availability. Demonstrate the continuity that the installed arrangement can provide and describe its boundary.
A fault-to-evidence acceptance matrix
Introduce faults only through an approved, reversible test procedure with a known recovery path. Start in a representative test environment and control any production verification with the site owner.
| Controlled fault | Function to observe | Evidence needed |
|---|---|---|
| Primary recording service stopped | Recording and live access | Playable timeline before, during and after |
| One network path unavailable | Sensor connectivity and buffering | Connection logs and data gap record |
| Event-processing service unavailable | Alarm delivery and acknowledgement | Test event IDs and receipt times |
| Storage temporarily unavailable | Recording health and recovery | Explicit fault status and retained evidence |
| Required identity service unavailable | Existing and new operator access | Supported access behavior |
| Primary service restored | Failback and data reconciliation | Duplicate, gap and backlog checks |
This matrix is a starting point. Choose fault methods and limits appropriate to the equipment and operational environment.
Why test failback separately?
Returning to the primary service can cause another interruption or expose inconsistent configuration. Data collected by the standby path may need to be copied, indexed or reconciled.
Check whether playback and export work across both transitions. Preserve original event IDs so replayed messages do not create duplicate incidents. Verify that the standby capacity becomes available again and that the system reports its restored protection state.
A platform that recovers service but remains unprotected after the test has not completed the recovery cycle.
Test the workload that matters
Include representative camera streams, analytics events, operator sessions and exports. A lightly loaded demonstration may not expose a shared standby server’s capacity limits when several services fail together.
Evaluate time synchronization during the transition. The camera time guide explains why a reordered timeline can look like missing or contradictory evidence. Review disk capacity with the video storage calculation rather than assuming the standby path has unlimited retention.
Report tested combinations and untested common dependencies. Do not generalize a single-service test into proof of resilience against every outage.
Turn the result into an operating procedure
Deliver measured recovery times, gap intervals, exported evidence, operator actions and unresolved limits. Record the installed versions and accepted configuration. Define retest triggers after software, storage, network or redundancy changes.
Keep the fault matrix, observed service gaps and recovery steps with the system handover. The next maintenance team should be able to repeat the test and recognize the same degraded states.
FAQs
Does a standby recorder protect the whole security system?
No. Cameras, power, network, identity, storage and other services may remain single points of failure. Define which functions the redundancy actually covers.
What is the difference between failover and failback?
Failover transfers work to a standby path or service. Failback returns it to the intended normal arrangement and may require data reconciliation.
Is a green server status enough to pass a failover test?
No. Verify the relevant operator functions, recording continuity, event delivery and exported evidence, including gaps or duplicates around the transition.